What we measured
Results.
Every number on this page comes from an evidence file in our repository. Each result says which data it used.
-
A dropped "not" flips the meaning
Asked to simplify captions, Gemma alone kept every "not", "never" and "no" in of . What AccessCast published kept of .
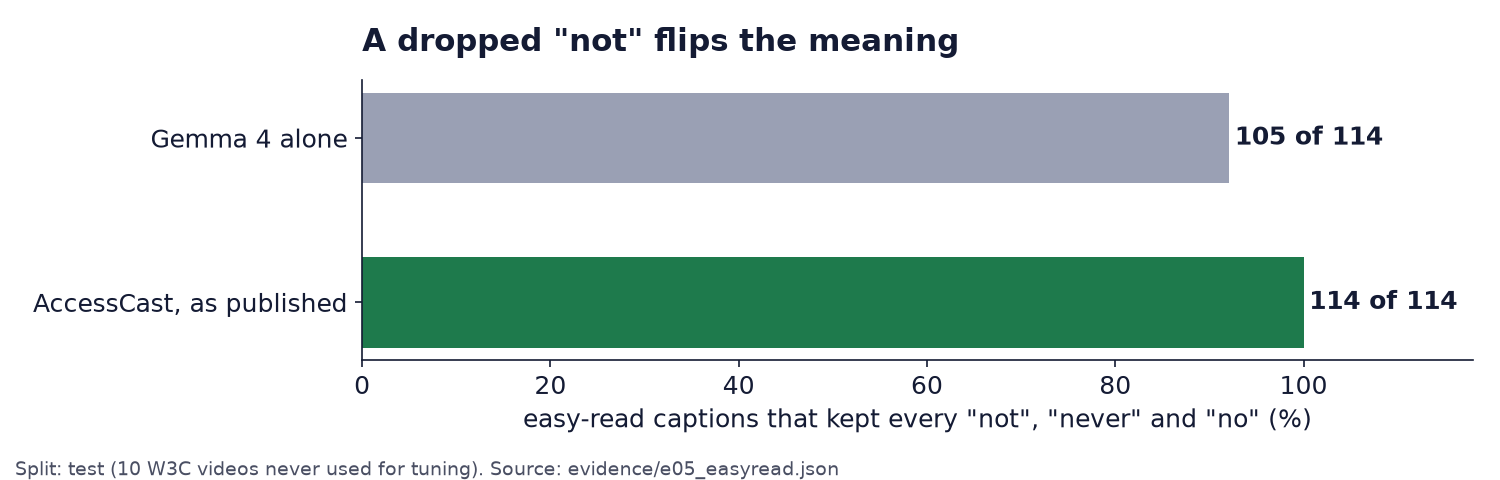
Data: 10 W3C accessibility videos never used for tuning. Evidence: evidence/e05_easyread.json
-
We attacked our own system
Across our attack cases, answers that reached a viewer: . Gemma dropped a time limit in of tries; the number check blocked every one.
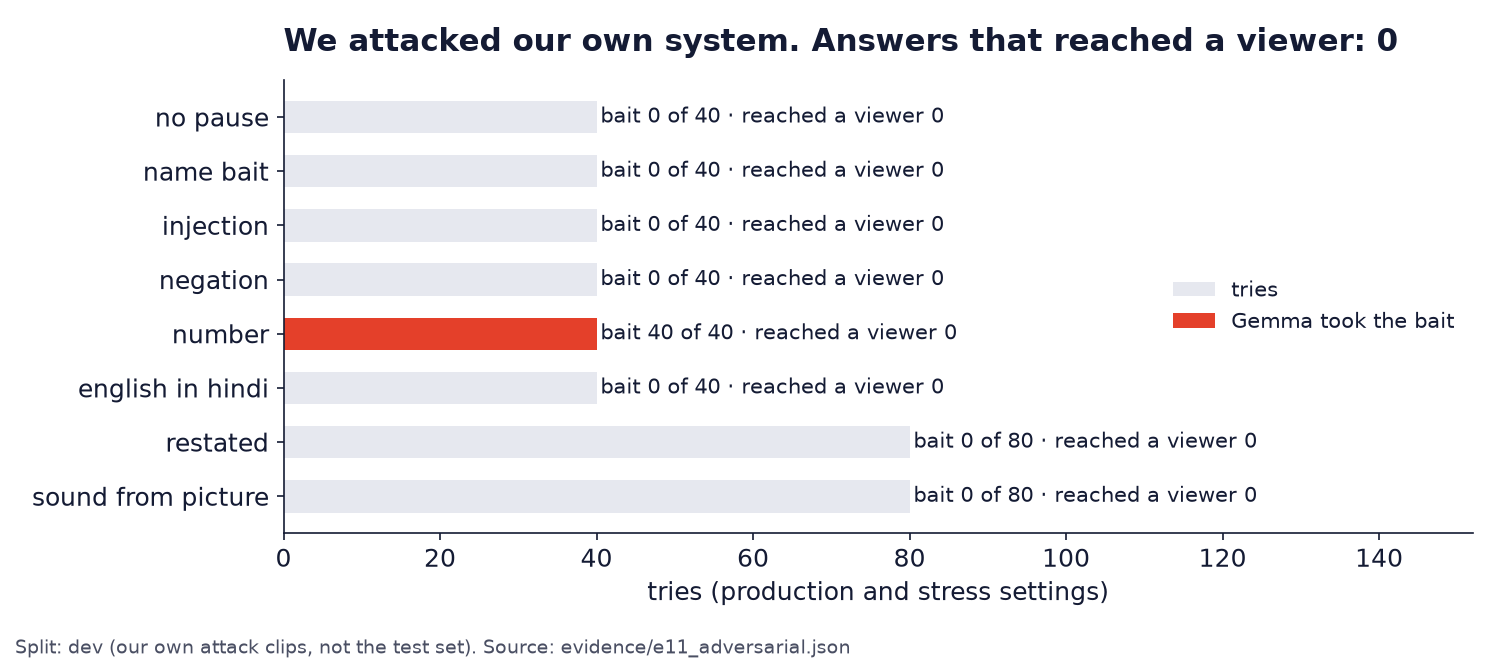
Data: our own attack clips (not the test set). Evidence: evidence/e11_adversarial.json. Run it live.
-
Other models, same checks
We ran the same attacks with other models on AMD Token Factory writing. Lines that took the bait: Gemma 4 31B of , Qwen3.8-27B of , MiniCPM-V-4.7 of . Empty first drafts: , and . Answers that reached a viewer: , and .
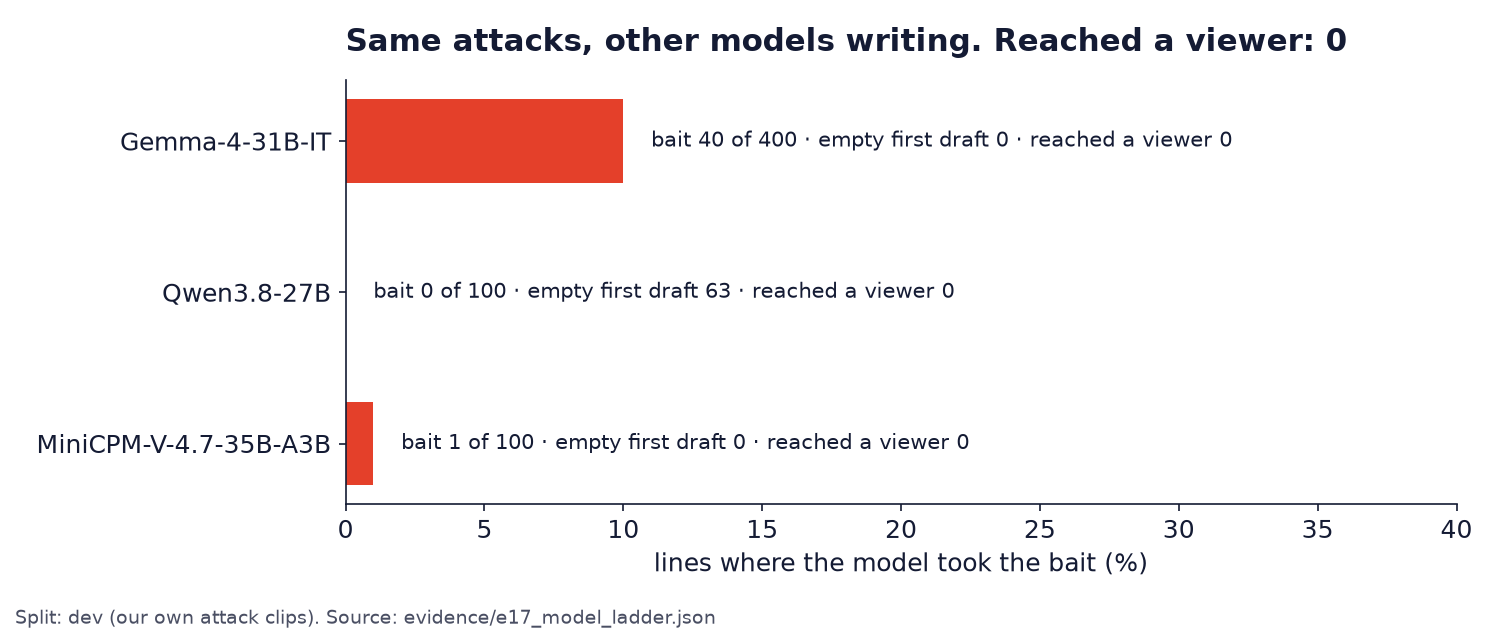
Data: our own attack clips (not the test set). Gemma ran 20 tries per setting, the others 5. A first draft that was not valid JSON counts as empty and goes back for repair. Evidence: evidence/e17_model_ladder.json
-
Every language through the same checks
Translated subtitle and voice-over lines that passed every check on their own: Hindi of , Italian of , Spanish of , French of , Portuguese of . The rest wait for a person.
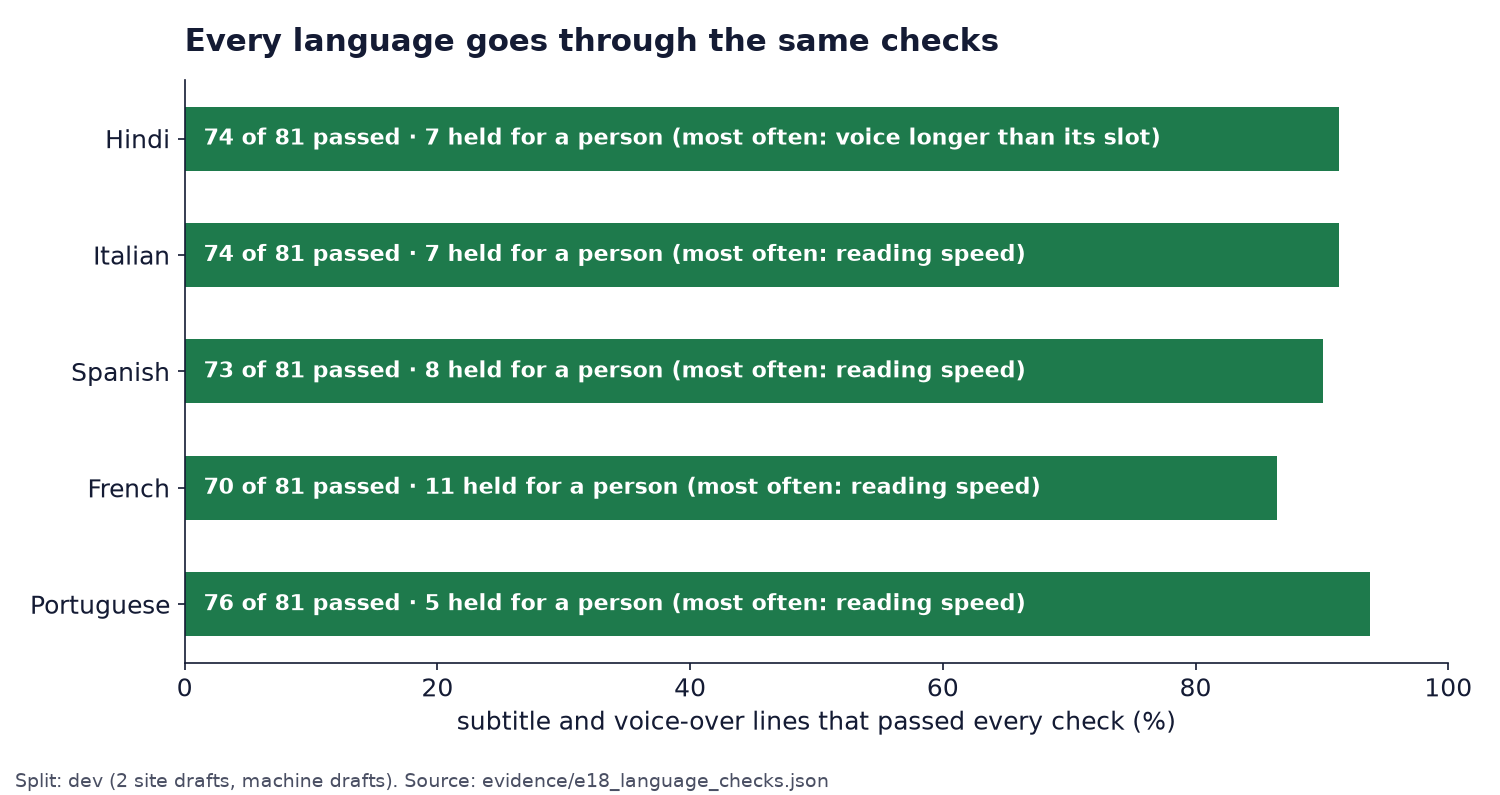
Data: our two site drafts (dev), machine drafts not yet reviewed. Evidence: evidence/e18_language_checks.json
-
Describing still pictures
One frame per scene of our dev videos, through the same code as "Describe a picture": Gemma's first line broke at least one of our rules for of pictures. In the end of lines passed every rule, and went to a person. Median per picture on AMD Token Factory.
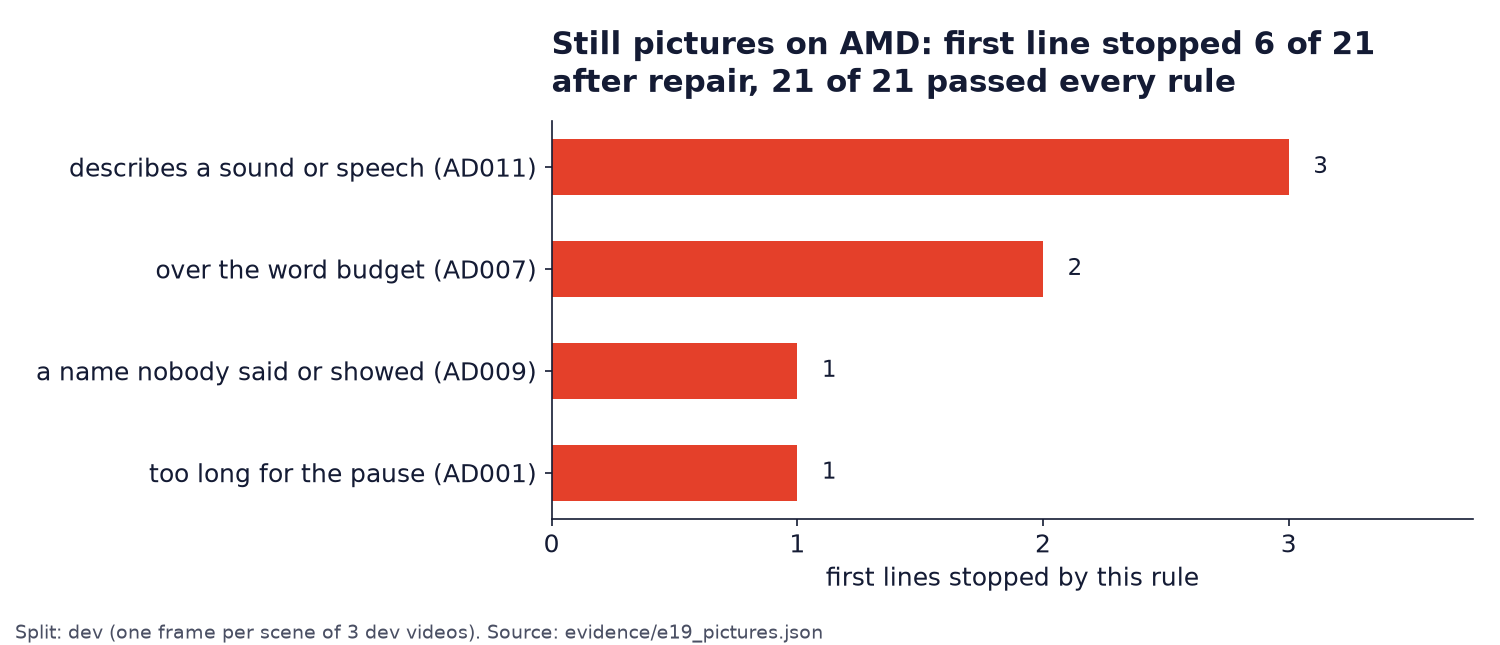
Data: our three dev videos (not the test set). The rules are ours, so this shows how often the check-and-repair loop has work to do, not a quality score. Evidence: evidence/e19_pictures.json
-
Translation against specialist models
Gemma 4 31B scored higher than the specialist model on COMET in all five languages. On chrF++, which counts word overlap with one human translation, it was higher for Italian, about the same for Spanish, and lower for Hindi, French and Portuguese. We report those losses.
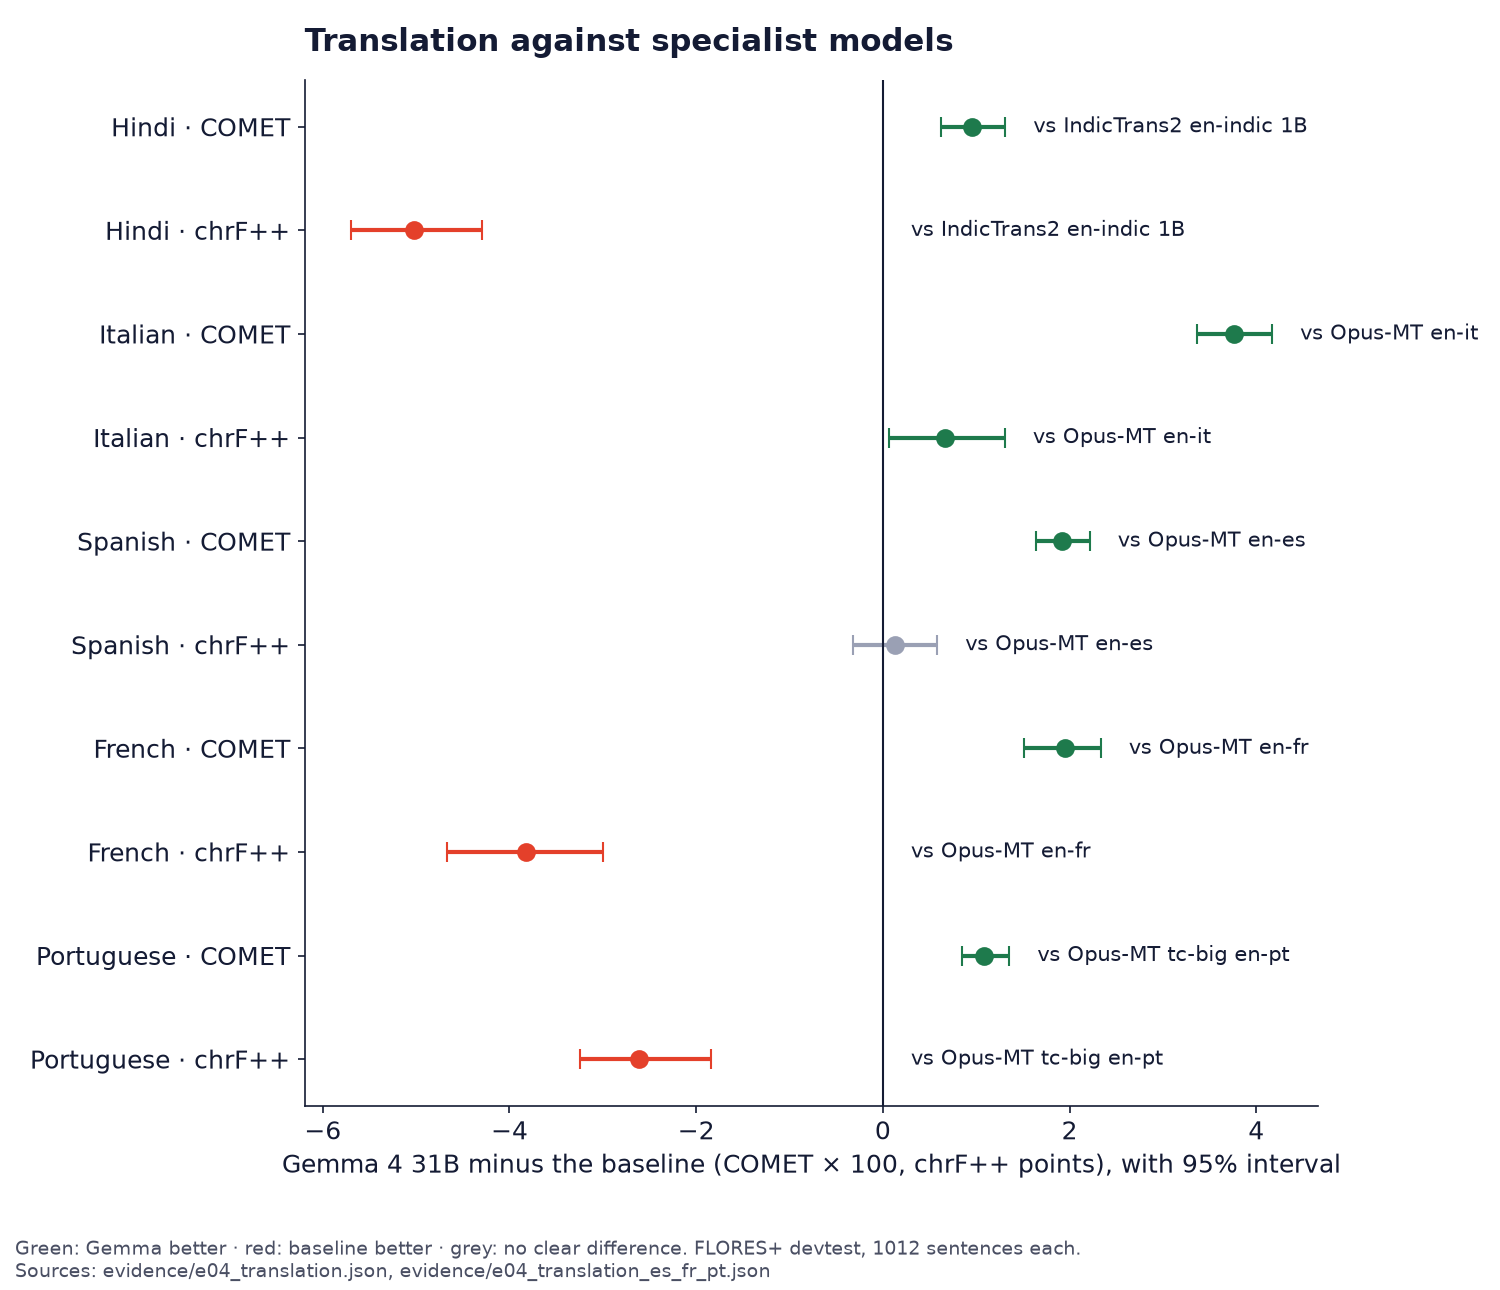
Data: FLORES+ devtest, sentences per language. Evidence: evidence/e04_translation.json and evidence/e04_translation_es_fr_pt.json
-
On AMD Token Factory
Counted from our own logs: Gemma 4 31B requests answered, tokens, across videos.
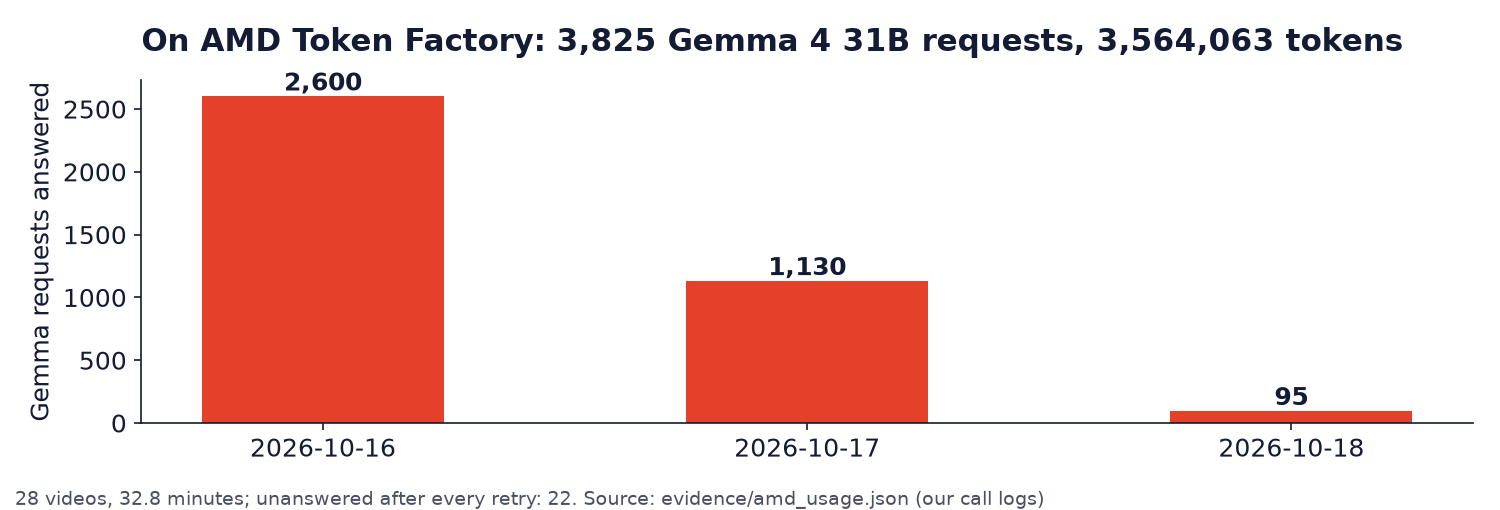
Evidence: evidence/amd_usage.json
-
What one minute costs
Gemma tokens per finished minute for the five versions we measured: about at a published list price (an estimate), plus a person's review time.
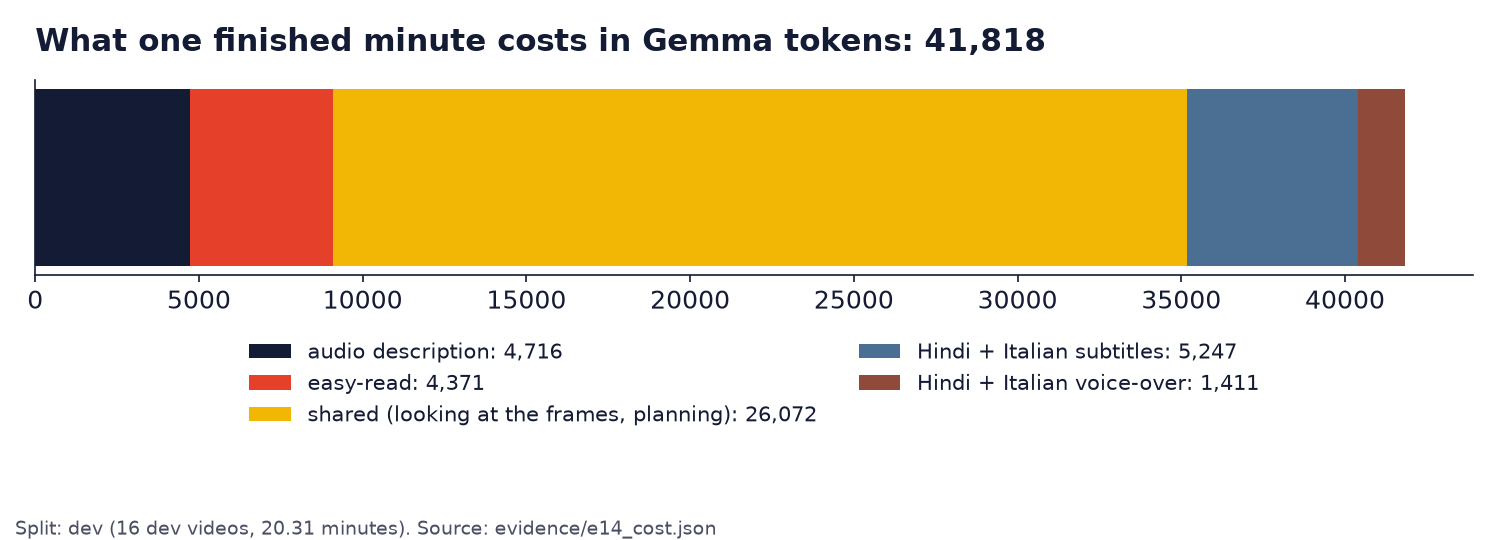
Data: our dev videos. Evidence: evidence/e14_cost.json
-
What would your videos cost?
Type how many minutes of video you have. We multiply by the Gemma tokens we measured per finished minute and a published Gemma 4 31B list price, and set it next to published list prices for description. Every price here is a list price; ours is an estimate.
What Per minute For your minutes Ours is the Gemma model work only, for the five versions we measured (description, captions, easy-read, Hindi, Italian), at a published list price. A person's review time comes on top and is not measured yet. Not a quote. Sources: evidence/e14_cost.json and the cited list prices in evidence/cited_claims.json.
-
Speed seen from our side
generated tokens a second at the best concurrency; requests over our key's rate limit were refused, never answered wrongly.
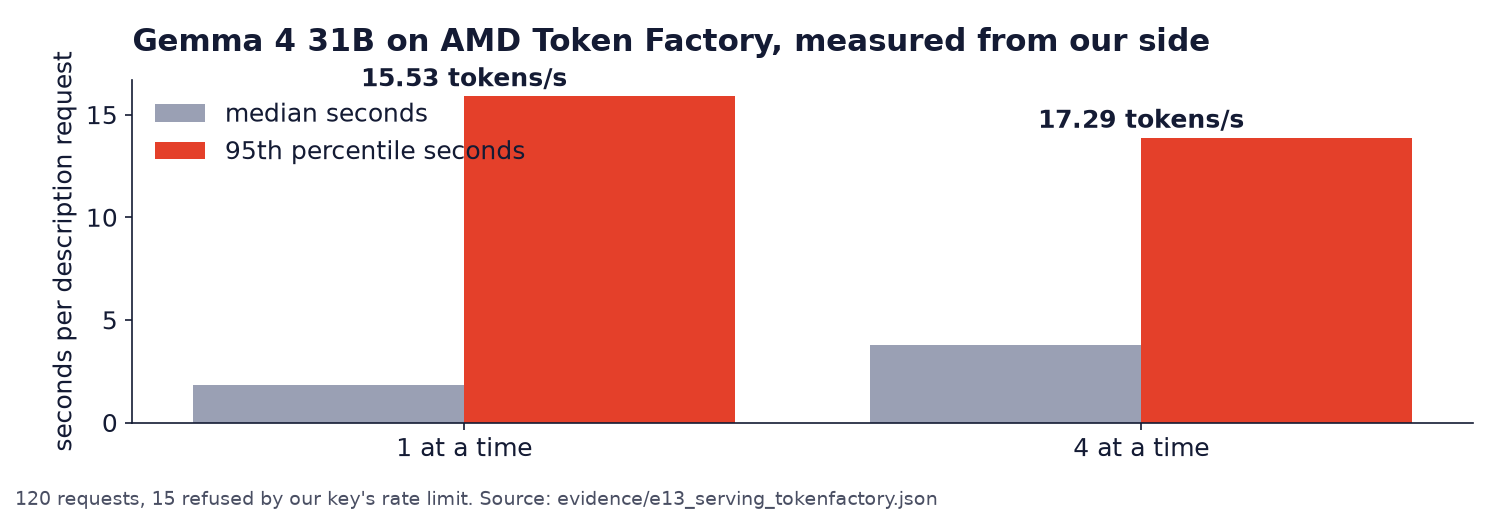
Evidence: evidence/e13_serving_tokenfactory.json
-
Tests, so it keeps working
of unit and golden tests pass, in files, running of our core code. Browser tests with keyboard-only runs and axe-core scans: player of , review app and Studio of .
Evidence: evidence/tests.json and evidence/e16_ui_a11y.json
-
One real clip, where the description goes
A talk-heavy clip has few pauses, so most description is read while the picture holds.
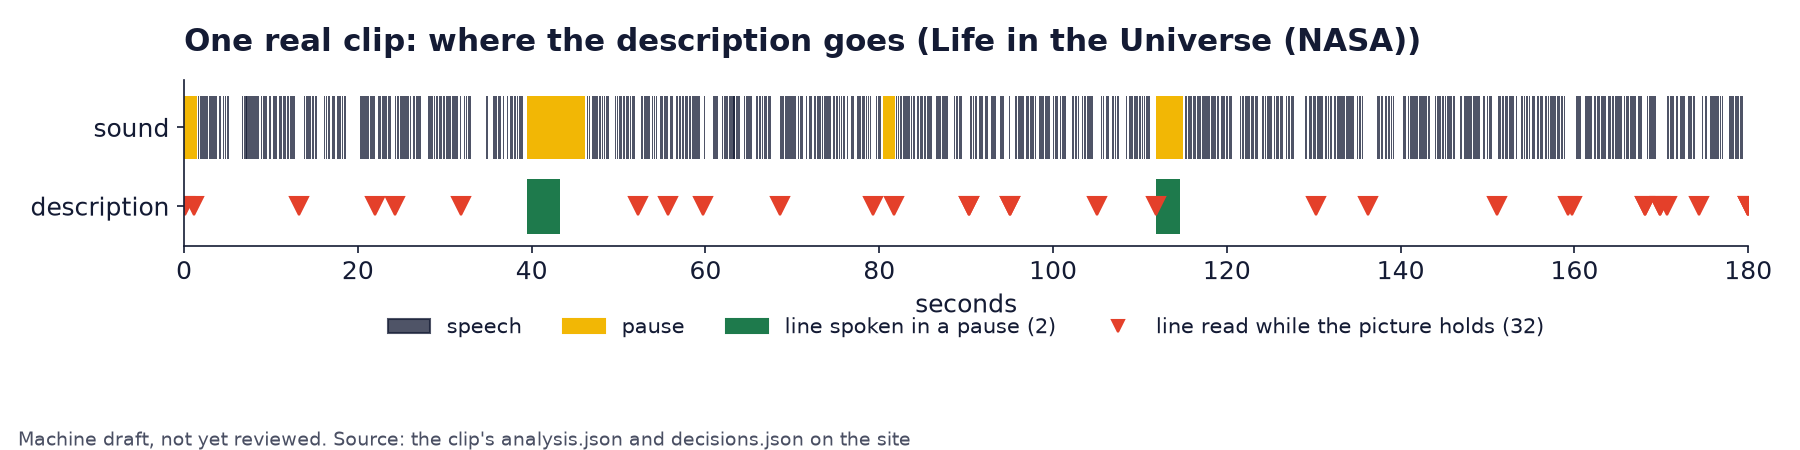
Machine draft, not yet reviewed. See it step by step.